E. Open-World and Open-Vocabulary Based Video Anomaly Detection#
Open-world and open-vocabulary VAD relax the closed-set assumption of conventional VAD, where anomaly categories are predefined and fixed by the benchmark. In real-world deployments, abnormal events may be rare, unseen during training, or described using flexible natural language concepts. Language models and vision-language models are therefore useful because they connect visual evidence with textual anomaly semantics through prompts, category descriptions, external knowledge, or user-defined anomaly definitions. In this setting, the main challenge is not only localizing anomalous segments, but also recognizing, describing, or reasoning about anomaly categories beyond the fixed training label space.
A representative starting point for this direction is OVVAD [127], which formulates open-vocabulary video anomaly detection as the joint problem of detecting and categorizing both seen and unseen anomalies. Unlike open-set VAD, which mainly aims to detect unseen anomalies without assigning them specific semantic categories, OVVAD requires the model to produce frame-level anomaly scores while also recognizing the anomaly category from an expandable label space. To address this problem, the method decouples OVVAD into two complementary components: class-agnostic detection and class-specific categorization. For detection, it uses CLIP visual features together with a lightweight temporal adapter and a semantic knowledge injection module that introduces normal and abnormal textual concepts from large language models. For categorization, it aligns video features with textual anomaly category embeddings and further introduces a novel anomaly synthesis module, where LLMs and generative models are used to create pseudo unseen anomaly samples. This design shows how vision-language models can extend VAD beyond closed-set abnormality scoring by combining temporal modeling, semantic knowledge, and generated novel-category supervision.
Following OVVAD, later works further improve open-vocabulary and open-world VAD by strengthening prompt adaptation, uncertainty modeling, and novel-category alignment. As illustrated in Figure 5, PLOVAD [129] adapts pretrained image-based vision-language models to OVVAD through prompt tuning rather than relying on generated pseudo-anomaly videos.
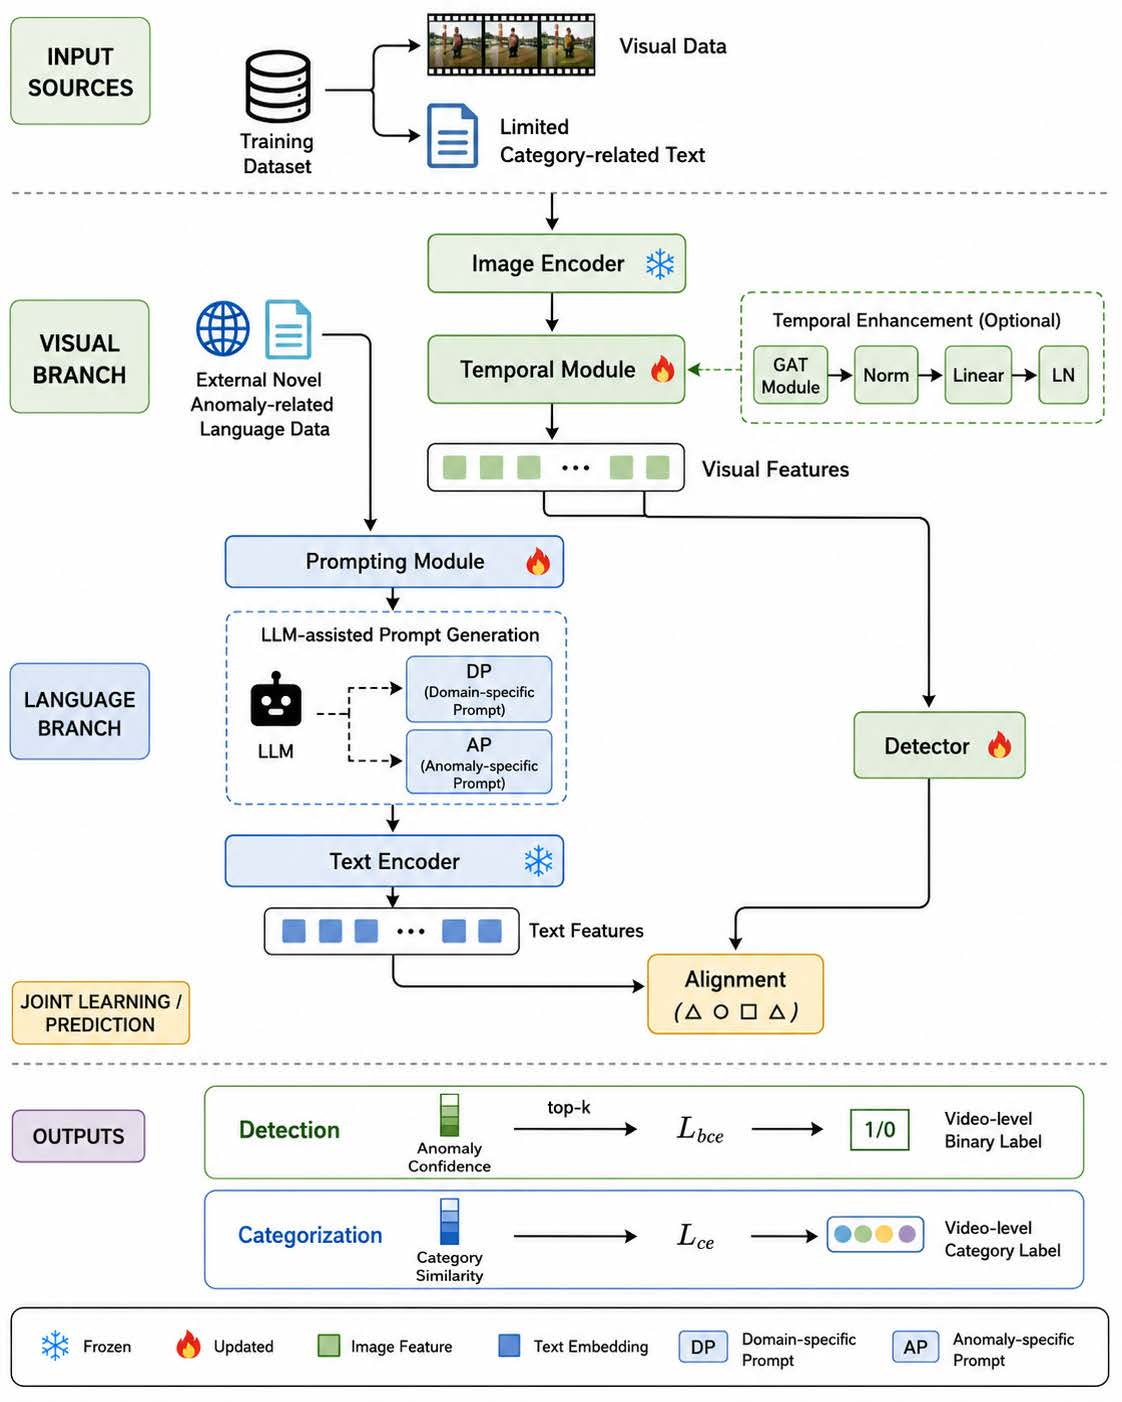
It introduces a prompting module with a learnable domain-specific prompt and an LLM-generated anomaly-specific prompt, allowing the model to capture both dataset-specific knowledge and semantic descriptions of anomaly categories. A GAT-based temporal module is further used to incorporate temporal dependencies into frame-wise VLM features, bridging the gap between image-level pretraining and video-level anomaly localization. In a related open-world weakly supervised setting, MEL-VLP [153] uses CLIP-derived visual and textual features together with multi-scale temporal visual modeling and multimodal evidential collaborative learning. Instead of treating anomaly prediction as a conventional confidence score, MEL-VLP collects visual, textual, and joint-modal evidence to estimate uncertainty and dynamically calibrate anomaly boundaries, which is especially useful when unseen anomalies appear at test time.
More recent methods focus specifically on the remaining challenges of novel anomaly detection and flexible anomaly definitions. Anomize [128] identifies two key issues in OVVAD: detection ambiguity, where unfamiliar anomaly frames receive unreliable anomaly scores, and categorization confusion, where novel anomalies are misclassified as visually similar base categories. To address these issues, it introduces a text-augmented dual-stream design that combines dynamic temporal cues and static scene cues with corresponding textual information, as well as a group-guided text encoding mechanism that uses label relations to improve alignment between novel videos and novel textual labels. LaGoVAD [154] further broadens the problem from open-vocabulary recognition to language-guided open-world VAD with variable anomaly definitions. Instead of assuming a fixed anomaly category set, LaGoVAD conditions anomaly detection on user-provided natural-language definitions at inference time, allowing the same event to be treated as normal or abnormal depending on context or user requirements. It implements this paradigm using language-guided video-text fusion, dynamic video synthesis, and contrastive learning with hard negative mining, supported by PreVAD [154], a large-scale dataset with multi-level anomaly categories and textual anomaly descriptions. Together, these methods show that open-world and open-vocabulary VAD is moving from recognizing unseen anomaly labels toward more flexible systems that can use language to define, detect, categorize, and reinterpret abnormal events in changing deployment contexts.