B. Weakly Supervised Video Anomaly Detection#
Weakly supervised video anomaly detection addresses the setting where training videos are labeled only at the video level, indicating whether each video contains an anomaly, while temporal or spatial annotations of anomalous regions are unavailable. This formulation is practically appealing because video-level labels are much easier to obtain than frame-level, segment-level, or pixel-level annotations, especially for long surveillance videos in which anomalous events are sparse and temporally localized. However, the lack of precise temporal supervision makes the task challenging: the model must infer which frames or snippets are responsible for the video-level abnormal label while avoiding overfitting to background, scene bias, or irrelevant contextual cues.
A seminal work in this setting is Sultani et al. [19], which formulated weakly supervised VAD as a multiple instance learning (MIL) problem. In this formulation, each video is treated as a bag of temporal instances, and abnormal videos are assumed to contain at least one anomalous instance, whereas normal videos contain only normal instances. The model is trained to assign higher anomaly scores to the most abnormal snippets in abnormal videos than to snippets in normal videos. This MIL-based formulation has strongly influenced subsequent weakly supervised VAD methods. Later works improved temporal localization by designing stronger feature representations, attention mechanisms, temporal context modeling, graph-based reasoning, pseudo-label refinement, and feature magnitude learning. For example, methods such as Zhong et al. [91], RTFM [111], MGFN [112], and related approaches further refined the weakly supervised paradigm by addressing noisy video-level labels, improving snippet discrimination, and modeling temporal dependencies more effectively.
Language-model-based weakly supervised VAD builds upon this MIL foundation but introduces language as an additional source of semantic guidance. Instead of relying only on visual features and video-level binary labels, recent methods use vision-language models, textual prompts, anomaly descriptions, captions, audio-visual-language cues, or LLM-derived knowledge to improve the alignment between visual events and anomaly semantics. This is particularly useful in weak supervision because the model does not observe exact anomaly boundaries during training; language can provide higher-level concepts such as "fighting," "explosion," "running," or "suspicious behavior" that help distinguish abnormal snippets from normal context. As a result, weakly supervised VAD has become one of the most active settings for language-model-based anomaly detection, with methods ranging from CLIP-based temporal localization and prompt learning to caption-guided reasoning, multimodal fusion, and LLM-enhanced knowledge transfer.
A major line of weakly supervised language-model-based VAD adapts pretrained vision-language models, particularly CLIP, to temporal anomaly localization. A representative weakly supervised CLIP-based pipeline is shown in Figure 2.
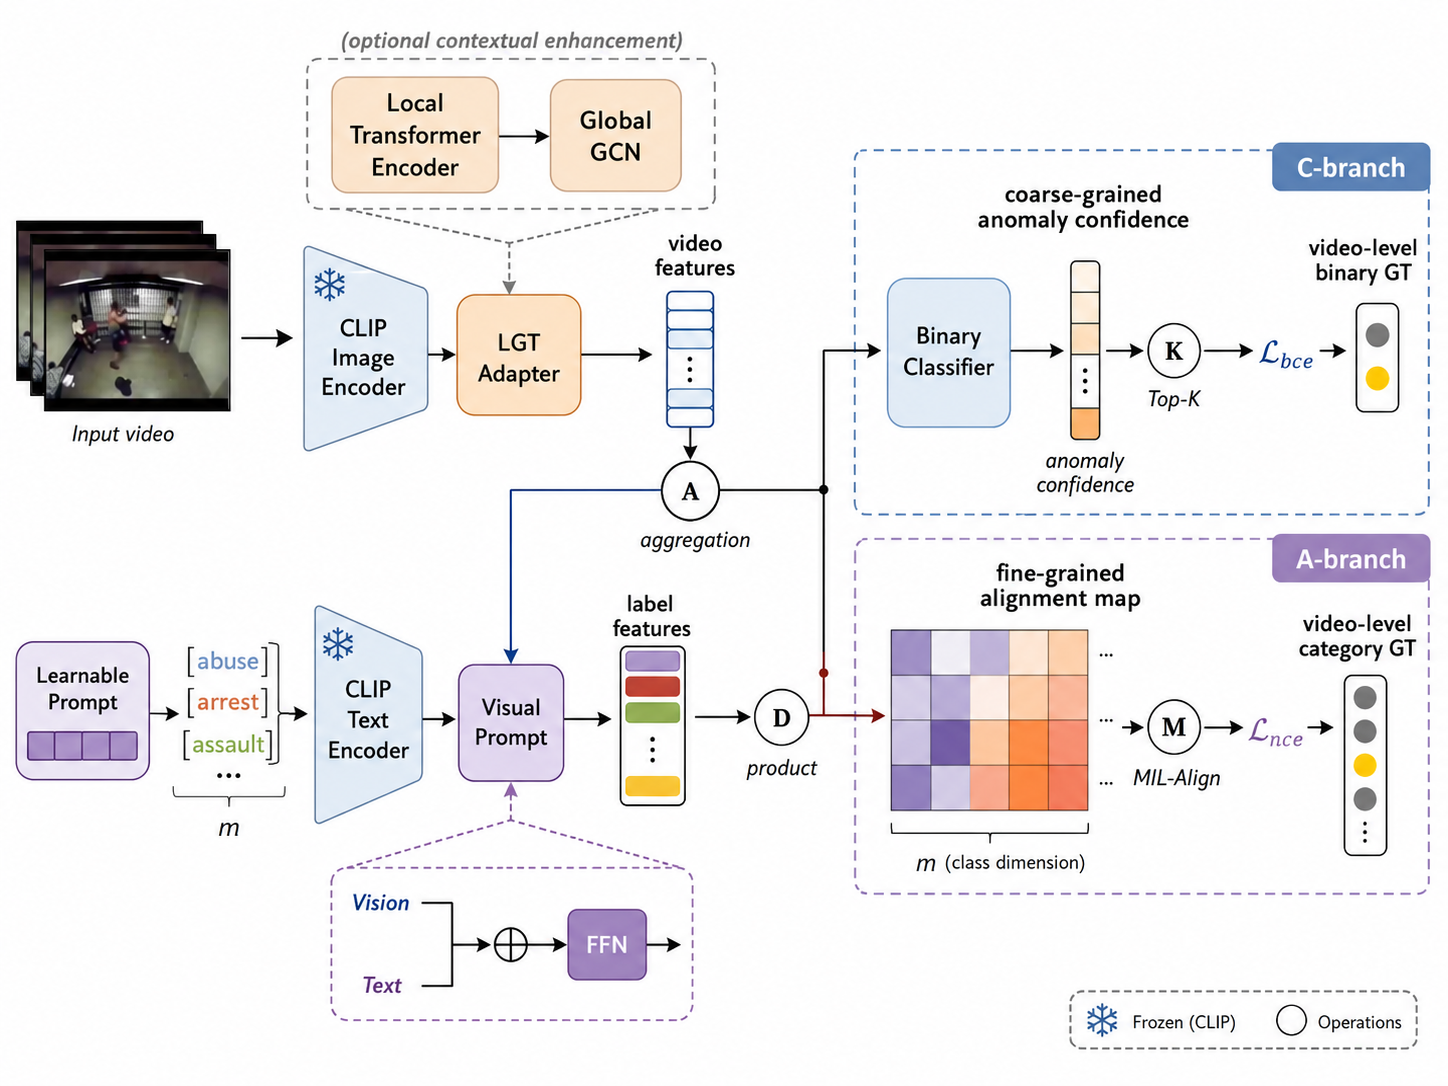
VadCLIP [88] introduces a dual-branch framework that combines a conventional visual classification branch with a vision-language alignment branch. The classification branch produces coarse-grained frame-level anomaly scores, while the alignment branch compares frame-level visual features with textual anomaly labels encoded by CLIP, enabling fine-grained anomaly recognition. To bridge the gap between image-level CLIP pretraining and video-level anomaly detection, VadCLIP introduces a local-global temporal adapter for temporal modeling, learnable textual prompts for adapting class labels to the VAD task, and anomaly-focused visual prompts that use visual context from likely abnormal snippets to refine text representations. It further proposes a MIL-Align objective to optimize video-text alignment under video-level supervision. Following this direction, later methods such as VadCLIP++ [99], WSVAD-CLIP [113], CLIP-TSA [104], CMSIL [108], ReFLIP-VAD [105], AnomalyCLIP [114], and VLIAL [105] further explore temporal modeling, prompt learning, feature refinement, multi-scale instance learning, and instance-aware vision-language alignment. Together, these methods demonstrate that CLIP-style visual-language representations can provide stronger semantic cues than visual-only MIL models, while still requiring task-specific temporal modules to localize anomalies from video-level labels.
Another group of weakly supervised methods focuses on prompt learning and text-prompt-enhanced MIL. Rather than using language only as fixed class names, these approaches design or learn prompts that provide additional semantic guidance for separating normal and abnormal snippets under video-level supervision. PEL [103] is representative of this direction. It combines a Temporal Context Aggregation module for efficient local-global temporal modeling with a Prompt-Enhanced Learning module that constructs knowledge-based prompts from external commonsense concepts. These prompt features are used during training to align anomalous visual contexts with semantically related textual concepts while pushing non-anomalous contexts away, thereby improving fine-grained discriminability among anomaly categories. Related methods [95], [96], [115]-[118] further explore spatiotemporal prompts, prompt-enhanced MIL objectives, opposite or suspected-anomaly prompts, multilingual prompt guidance, and federated multimodal prompt learning. Overall, this family shows that prompt design can act as an intermediate semantic constraint between weak video-level labels and frame-level anomaly localization.
A related direction uses captions, textual clues, and semantic summaries to provide higher-level guidance for weakly supervised VAD. Unlike prompt-learning methods that mainly adapt class names or prompt templates, these approaches use language to describe video content more explicitly and to enrich visual representations with event-level semantics. TEVAD [110] is representative of this line of work. It first generates dense captions for video snippets using a pretrained captioning model, encodes the captions into sentence embeddings, and processes both textual and visual features with temporal networks before multimodal fusion and MIL-based anomaly scoring. By incorporating caption-derived semantic features, TEVAD improves detection performance while also providing a degree of interpretability through the contribution of individual caption words to anomaly scores. Subsequent semantic-guided methods [93], [97], [98], [119] further explore the use of injected text clues, semantic filtering and summarization, event completeness modeling, and representative temporal feature learning. Overall, this family highlights the role of language as descriptive evidence, complementing visual MIL models with semantic information that is difficult to capture from spatio-temporal features alone.
Another line of weakly supervised language-model-based VAD moves beyond CLIP-style feature adaptation and uses LLMs or MLLMs for knowledge enhancement, token alignment, distillation, and explainability. Ex-VAD [94] is representative of this direction. It first uses a VLM to generate frame-level captions and an LLM to convert them into video-level anomaly explanations, which are then used both as interpretable outputs and as textual features for multimodal anomaly detection. In addition, Ex-VAD augments anomaly category labels with LLM-generated descriptive phrases and aligns these enhanced label embeddings with fused visual-textual features to support fine-grained anomaly classification. CALLM [120] explores a related but more cascaded design, where a 3D autoencoder first identifies suspicious frames or videos and a Video-LLaMA branch is then used to provide abnormality decisions and explanations through weakly supervised pseudo-instruction tuning. Other methods in this family, [92], [106], [109], [121] investigate how language-model knowledge, anomaly-relevant token alignment, and knowledge distillation can improve weakly supervised anomaly localization. Overall, these methods show a shift from using language only as class-level semantic anchors toward using LLMs and MLLMs as sources of explanatory reasoning, enriched anomaly knowledge, and transferable supervision.
Another extension of weakly supervised language-model-based VAD incorporates additional modalities, especially audio, to improve robustness in visually ambiguous scenes. Audio-visual fusion has also been explored in conventional non-LM VAD, providing useful methodological context for recent language-based multimodal systems. For example, M2VAD [122] combines multi-view visual information with audio in a transformer-based weakly supervised framework, demonstrating the complementary value of acoustic cues for anomaly representation. AVadCLIP [101] is a language model based representative of this direction. Building on the CLIP-based weakly supervised paradigm, AVadCLIP introduces audio-visual adaptive fusion to combine visual features with audio features in a lightweight manner while keeping the CLIP backbone frozen. It further designs an audio-visual prompt that injects multimodal information into textual label embeddings, improving the alignment between anomalous video content and anomaly categories. To handle practical cases where audio may be unavailable at inference time, AVadCLIP also introduces uncertainty-driven feature distillation, transferring audio-visual knowledge to a visual-only student model. Related multimodal methods [102], [107], [123] further explore audio-vision-language fusion, heterogeneous cross-modal knowledge transfer, and adaptive multimodal feature integration. Overall, this family shows that language-based VAD can benefit from multimodal cues beyond vision, particularly for anomalies with strong acoustic signatures or degraded visual evidence.
Finally, several recent works extend weakly supervised language-model-based VAD beyond standard MIL-style detection by introducing relation-aware, structured, or retrieval-oriented formulations. RelVid [100] uses CLIP-based visual and textual representations together with auxiliary anomaly recognition and reconstruction objectives to improve class separation and temporal feature learning. MISSIONGNN [124] further incorporates structured reasoning by generating mission-specific knowledge graphs with an LLM and ConceptNet, then applying hierarchical GNNs over these graphs for weakly supervised anomaly recognition. In a different direction, ALAN [125] shifts from anomaly detection to video anomaly retrieval, where long untrimmed videos are retrieved using textual descriptions or audio queries; it introduces anomaly-led sampling and cross-modal alignment to focus retrieval on relevant anomalous segments. Although these methods differ from the main CLIP, prompt, and caption-based detection pipelines, they illustrate how language can support broader forms of anomaly understanding, including semantic relation modeling, knowledge-guided reasoning, and retrieval from descriptive queries.
Overall, LM-based weakly supervised VAD methods extend the classical MIL formulation by incorporating vision-language alignment, prompt learning, caption-derived semantics, LLM-enhanced anomaly knowledge, multimodal fusion, and relation-aware reasoning. Table 5 summarizes representative weakly supervised VAD methods on UCF-Crime, XD-Violence, and ShanghaiTech, comparing classical non-LM baselines with recent LM-based approaches.
TABLE 5. WVAD methods on UCF-Crime (UCF), XD-Violence (XD), and ShanghaiTech (SHTech). Values are taken from the corresponding source publications.
| Method | Year | UCF (AUC) | XD (AP) | SHTech (AUC) |
|---|---|---|---|---|
| *Classical (non-LM) weakly-supervised methods* | ||||
| MSL [89] | 2022 | 85.62% | 78.59% | 97.32% |
| MIST [90] | 2021 | 82.30% | - | 94.83% |
| GCN [91] | 2019 | 82.12% | - | 84.44% |
| DeepMIL [19] | 2018 | 75.40% | - | - |
| *LM-based weakly-supervised methods* | ||||
| DAKD [92] | 2025 | 88.34% | 85.61% | 98.10% |
| LEC-VAD [93] | 2025 | 89.97% | 86.56% | - |
| Ex-VAD [94] | 2025 | 88.29% | 86.52% | - |
| Federated-WVAD [95] | 2025 | 84.03% | 75.99% | - |
| LOP-VAD [96] | 2025 | 88.07% | 86.18% | - |
| TCRFL [97] | 2025 | 87.31% | 82.63% | 98.12% |
| FSA-VAD [98] | 2025 | - | - | 97.66% |
| VadCLIP++ [99] | 2025 | 88.12% | 85.03% | - |
| RelVid [100] | 2025 | 87.71% | 80.76% | - |
| AVadCLIP [101] | 2025 | - | 86.04% | - |
| Multimodal-VAD [102] | 2025 | 87.96% | 86.32% | - |
| PEMIL [103] | 2024 | 86.76% | 85.59% | 98.14% |
| VadCLIP [88] | 2024 | 88.02% | 84.51% | - |
| CLIP-TSA [104] | 2024 | 87.58% | 82.19% | 98.32% |
| ReFLIP-VAD [105] | 2024 | 89.14% | 86.29% | - |
| IELD-WVAD [106] | 2024 | 89.67% | 85.92% | - |
| DWFF-VAD [107] | 2024 | 88.58% | 85.58% | - |
| CMSIL [108] | 2024 | 87.57% | 86.06% | - |
| WSVAD-LLMKE [109] | 2024 | 86.88% | 87.05% | 98.25% |
| TEVAD [110] | 2023 | 85.30% | - | - |