A. Unsupervised and Semi-Supervised VAD#
The boundary between unsupervised and semi-supervised video anomaly detection is often blurred in the VAD literature. Many methods described as "unsupervised" are in fact trained on videos that are assumed to contain only normal events, which corresponds more closely to one-class or semi-supervised anomaly detection in the broader machine learning terminology. Conversely, some recent language-model-based methods operate with unlabeled or weakly constrained data, but still rely on normal reference samples, scene-specific prompts, or induced normality rules. For this reason, we discuss unsupervised and semi-supervised LM-based VAD together under a broader normality-learning perspective.
In this setting, the central assumption is that anomalous events are not explicitly available during training. Instead, the model learns, constructs, or infers a representation of normal behavior, and anomalies are detected as deviations from this representation during inference. Classical approaches typically define such deviations through reconstruction error, prediction error, likelihood, memory retrieval, or distance from a learned normal manifold. Language-model-based methods extend this paradigm by shifting normality modeling from purely visual statistics toward semantic representations, textual descriptions, vision-language similarity, rule induction, and multimodal reasoning.
Early normality-learning VAD methods primarily detected anomalies as deviations from learned regular visual patterns, using reconstruction, prediction, memory, or sparse representation mechanisms. Lu et al. [20] introduced an efficient sparse-reconstruction-based approach, where normal patterns are compactly represented and abnormal events are identified through high reconstruction cost. Hasan et al. [17] later used autoencoders to learn temporal regularity in video sequences, treating large reconstruction or regularity errors as evidence that an event violates learned spatio-temporal patterns. Liu et al. [18] shifted this idea toward future-frame prediction, where anomalies are detected through large prediction errors on events that cannot be reliably forecast from normal training videos. Memory-based extensions further improved this paradigm: Gong et al. [80] introduced MemAE, which constrains reconstruction through a memory module containing prototypical normal patterns to reduce the risk of reconstructing anomalies too well, while Liu et al. [86] combined memory-augmented optical-flow reconstruction with flow-guided frame prediction to better capture normal appearance-motion consistency. Together, these works established the dominant foundation of unsupervised and semi-supervised VAD: anomalous events are not directly modeled during training, and detection depends on how effectively the learned normality representation separates regular behavior from abnormal deviations.
A first group of LM-based normality-learning methods shifts anomaly detection from low-level visual reconstruction toward language-aligned semantic representations of normal behavior. Instead of modeling normality only through appearance, motion, or reconstruction errors, these methods use VLMs or MLLMs to represent frames, objects, trajectories, or interactions in a semantic space, and then detect anomalies as rare, inconsistent, or distant semantic patterns. VLAVAD [84] is an early example of this direction. It detects and tracks objects, queries a pretrained VLM with selected prompts for each object crop, and uses the resulting semantic responses to describe object appearance, pose, and action. A Selective Prompt Adapter selects the prompt that best concentrates normal samples in the semantic space, while a Sequence State Space Module predicts future semantic embeddings from normal object-level sequences. Anomalies are therefore detected through both rare semantic responses and temporal inconsistencies between predicted and observed semantic states. Figure 1 illustrates a representative semi-supervised LM-based VAD pipeline, where object-centric visual evidence is converted into textual descriptions and compared against normality exemplars.
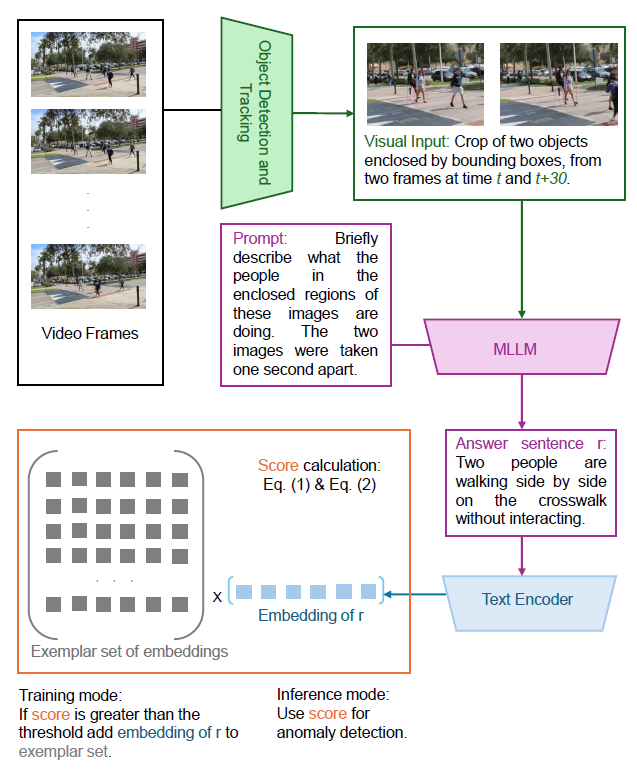
MLLM-EVAD [79] follows a related object-centric direction, but uses MLLM-generated descriptions of single-object activities and object-pair interactions as scene-specific normality exemplars. At inference time, new descriptions are compared with compact nominal exemplar sets, allowing anomaly scores to be computed from semantic distance while also providing textual evidence for the detected abnormality. Kim et al. [87] provide a simpler CLIP-based variant of semantic normality modeling, where frames or object crops are compared with predefined natural-language descriptions of normal and abnormal situations generated with ChatGPT and adapted to the target domain. Their method further learns a text-conditional similarity function without frame- or video-level anomaly labels, making it computationally simpler than object-trajectory-based approaches, although less explicit in modeling long-range temporal dynamics.
A complementary direction retains the classical prediction-based normality-learning paradigm, but extends it with semantic consistency. SFN-VAD [83] combines appearance, motion, and language-derived semantic cues for semi-supervised VAD. The method uses a VLM to generate textual descriptions of input clips, encodes them as semantic features, and fuses them with visual appearance and frame-difference-based motion features through a tri-modal encoder. A multimodal decoder then predicts both the next frame and the corresponding semantic representation, so anomaly scores can be computed from visual prediction errors as well as semantic prediction errors. To reduce excessive generalization to abnormal events, SFN-VAD further introduces a Sparse Feature Filtering Module with bottleneck filters and mixture-of-experts routing. In this way, it extends reconstruction- and prediction-based normality learning beyond low-level appearance and motion by explicitly modeling whether future visual content and future semantic descriptions remain consistent with normal behavior.
Another group of LM-based normality-learning methods uses LLMs and VLMs to induce, retrieve, or validate semantic rules about normal and abnormal behavior. AnomalyRuler [85] is representative of this direction. Given a few normal reference frames, a VLM first converts the scene into textual descriptions, and an LLM then derives scenario-specific rules describing normal human activities, environmental objects, and possible abnormal deviations. During inference, test-frame descriptions are matched against these induced rules and refined through perception smoothing and robust LLM-based reasoning. This induction-deduction formulation allows the method to adapt to different scenes without anomalous training examples or full-shot detector training. SlowFastVAD [82] extends this idea with a RAG-enhanced vision-language pipeline: a fast reconstruction-based detector first identifies ambiguous segments, and only these segments are passed to a slower VLM-based module that retrieves normal and potential abnormal patterns from a scenario-specific knowledge base to generate anomaly scores and interpretable reasoning. HyCoVAD [81] follows a related detect-then-validate strategy for complex interaction anomalies, where a self-supervised detector first selects suspicious frames from low-level spatiotemporal deviations, and a VLM/LLM-based validation stage uses refined captions and environment-specific rules to decide whether the event is anomalous. Together, these methods show that LLMs can support semi-supervised or one-class VAD not only by providing semantic representations, but also by constructing explicit normality rules, retrieving contextual knowledge, and applying reasoning selectively to reduce the cost of dense MLLM inference.
Overall, LM-based unsupervised and semi-supervised VAD methods extend normality learning beyond reconstruction, prediction, and memory-based modeling by incorporating semantic representations, textual descriptions, rule induction, retrieval, and MLLM-based reasoning. The quantitative results summarized in Tables 4-6 are reported values taken from the corresponding original publications; they were not reproduced under a unified experimental setup for this survey. This follows the common convention in the VAD literature, where comparison tables typically report results from the source papers and independently reproduced results are explicitly identified when applicable. The standard VAD benchmarks considered in these tables generally provide established training and testing partitions, and methods evaluated on the same benchmark typically use these common splits. Nevertheless, the numbers should be interpreted as representative reference points rather than as strictly controlled cross-method comparisons. Differences in feature extractors, pretrained backbones, frame or clip sampling and frame rate, temporal processing, anomaly-score smoothing and other post-processing, external training data, and implementation details can influence the reported performance even when the same benchmark and evaluation metric are used. Table 4 summarizes representative semi-supervised VAD methods on commonly used benchmarks, including Ped2, CUHK Avenue, ShanghaiTech, UBnormal, and ComplexVAD, comparing classical non-LM baselines with recent LM-based methods.
TABLE 4. SVAD methods on Ped2 (Ped2), CUHK Avenue (Avenue), ShanghaiTech (SHTech), UBnormal (UBnormal), and Complex-VAD (CVAD). Values are taken from the corresponding source publications.
| Method | Year | Ped2 (AUC) | Avenue (AUC) | SHTech (AUC) | UBnormal (AUC) | CVAD (AUC) |
|---|---|---|---|---|---|---|
| *Classical (non-LM) semi-supervised methods* | ||||||
| FutureFrame [18] | 2018 | 95.4% | 85.1% | 72.8% | - | - |
| MemAE [80] | 2019 | 94.1% | 83.3% | 71.2% | - | - |
| *LM-based semi-supervised methods* | ||||||
| HyCoVAD [81] | 2025 | - | - | - | - | 72.5% |
| MLLM-EVAD [79] | 2025 | - | 88.4% | - | - | 71.0% |
| SlowFastVAD [82] | 2025 | 99.1% | 89.6% | 85.0% | 72.2% | - |
| SFN-VAD [83] | 2025 | 98.4% | 91.6% | 83.0% | - | - |
| VLAVAD [84] | 2024 | - | 87.2% | - | - | - |
| Follow the Rules [85] | 2024 | 97.9% | 89.7% | 85.2% | 71.90% | - |