Introduction#
Video Anomaly Detection (VAD) has become a vital technology in intelligent surveillance and public safety, aiming to automatically identify behaviors or events that deviate from expected patterns. More broadly, anomaly detection has long been studied as the problem of identifying rare observations that deviate from expected data regularities [1], [2]. Anomalies can be viewed as spatial, temporal, or semantic deviations, such as an unauthorized object in a restricted area, a vehicle moving against traffic, or high risk behaviors such as armed conflict. For decades, research in VAD has sought to build automated systems that flag these rare and unpredictable events. Early approaches primarily relied on hand-crafted feature engineering, where researchers designed discriminative features tailored to specific scenes [3]-[15]. However, these methods often lacked the robustness required for complex and dynamic real world environments.
The advent of deep learning marked a significant milestone, driving innovation in VAD methodologies and substantially improving performance. Deep neural networks (DNNs) moved the field away from manual feature design by learning powerful feature representations directly from data [16]-[19]. This era was characterized by several key paradigms. Self-supervised methods for semi-supervised VAD learned patterns of normal events by training models on tasks such as future frame prediction [18] or video reconstruction [20], then flagged deviations from these learned norms as anomalies. For weakly supervised scenarios, where only video level labels are available, Multiple Instance Learning (MIL) [19] became a dominant approach, enabling models to localize anomalous segments without requiring precise temporal annotations. Despite their success, these DNN based methods share a fundamental characteristic: they operate primarily within the *visual feature space*. This foundation leads to persistent challenges, including limited generalization to unseen scenarios and a lack of interpretability, since the models' decision making processes remain largely opaque. Moreover, performance gains on several widely used benchmarks have become incremental in recent years, underscoring the need for new methodological advances.
A major turning point has emerged with the rapid advancement of Large Language Models (LLMs) and Multimodal Large Language Models (MLLMs), which are reshaping video anomaly detection (VAD). This transformation is reflected in publication trends, as summarized in Figure 1.
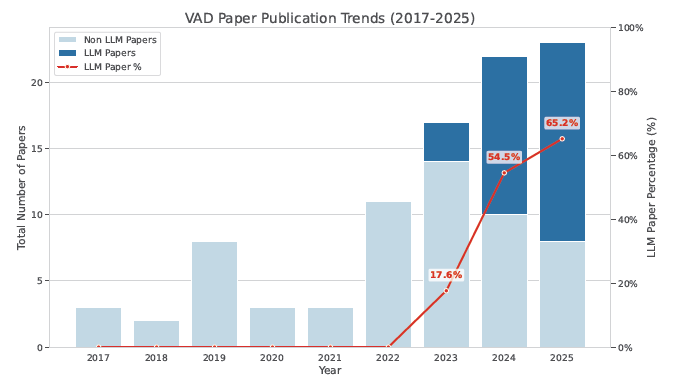
The timing also coincides with the introduction of foundational vision language models such as CLIP [21] in 2021. An analysis of top tier conferences, including CVPR, ICCV, ECCV, WACV, NeurIPS, and ICML, suggests that after an initial adoption period, a first notable wave of LLM based VAD studies appeared in 2023, accounting for 17.6% of VAD publications at these venues, including three papers at CVPR (see Table 1). This trend accelerated in subsequent years. By 2024, LLM based papers surpassed traditional methods to reach a 54.5% majority (12 papers), increasing further to 65.2% (15 papers) in 2025.
The significance of this trend, detailed in Table 1, extends beyond vision centric venues. General machine learning conferences, which previously featured very few VAD studies (for example, only one paper total until 2024), have since experienced a substantial increase. By 2025, NeurIPS and ICML together published nine VAD papers. As Table 1 shows, eight of these were based on LLMs, accounting for 86% of VAD papers at NeurIPS (6 papers) and 100% at ICML (2 papers). This expansion highlights the field's growing presence in model centric venues and a shift toward approaches that emphasize high-level reasoning in addition to low-level visual patterns.
TABLE 1. VAD Paper Trends by Conference. Cell format: Non-LLM / LLM (LLM %).
| 2017 | 2018 | 2019 | 2020 | 2021 | 2022 | 2023 | 2024 | 2025 | |
|---|---|---|---|---|---|---|---|---|---|
| CVPR | 1/0 (0%) | 1/0 (0%) | 3/0 (0%) | 1/0 (0%) | 1/0 (0%) | 2/0 (0%) | 5/3 (38%) | 4/5 (56%) | 3/4 (57%) |
| ICCV | 1/0 (0%) | - | 3/0 (0%) | - | 2/0 (0%) | - | 4/0 (0%) | - | 2/1 (33%) |
| ECCV | - | 0/0 (0%) | - | 1/0 (0%) | - | 4/0 (0%) | - | 2/3 (60%) | - |
| WACV | 1/0 (0%) | 1/0 (0%) | 2/0 (0%) | 1/0 (0%) | 0/0 (0%) | 4/0 (0%) | 5/0 (0%) | 3/2 (40%) | 2/2 (50%) |
| NeurIPS | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 1/0 (0%) | 0/0 (0%) | 1/2 (67%) | 1/6 (86%) |
| ICML | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/0 (0%) | 0/2 (100%) |
This new phase of VAD research is characterized by a move from pixel level pattern recognition toward semantic reasoning. In contrast to traditional deep neural networks, MLLMs can leverage large scale pretraining, world knowledge, and language supervision to interpret video content at a higher semantic level [21]-[26]. They can abstract raw visual inputs into semantic representations, analyze contextual relationships, and assess whether an observed action is anomalous relative to the scene context. This shift has not only improved detection performance in several recent works, but has also motivated new directions, including *Training Free VAD*, *Instruction Tuning VAD*, and *Open Vocabulary VAD*.
While Figure 1 and Table 1 illustrate the rapid rise of language models in VAD within top tier conferences, this trend reflects a much broader proliferation. In the past three years alone, over one hundred LM based VAD papers have been published. This growth motivates a comprehensive and systematic analysis of the field. Although several surveys have addressed Video Anomaly Detection (VAD), they often have specific limitations. The review by Ramachandra et al. [27], for instance, centers on semi-supervised VAD but is focused on single-scene scenarios and does not cover other settings. Similarly, Nayak et al. [28] provided a comprehensive look at deep learning for semi-supervised VAD but did not extend their analysis to other VAD paradigms. Other works, such as Tran et al. [29], examined weakly supervised methods but did not focus exclusively on VAD, since they also considered image anomaly detection. Although Liu et al. [34] proposed useful classification frameworks for semi supervised and weakly supervised tasks, their coverage predates many recent developments. More recently, Wu et al. [31] offered detailed insights across a range of VAD tasks, including unsupervised and open set methods. However, their treatment of MLLM and LLM based approaches was not in depth, providing only a high level overview and not capturing the impact of these newer techniques on the field.
Gao et al. [35] propose a unified perspective spanning DNN based and MLLM based approaches and are correspondingly broad in scope. While that work was among the first to analyze MLLM based methods at scale, its goal of covering the entire VAD landscape naturally limits the depth of discussion on architectural choices, prompt and instruction design, and the challenges unique to language model driven pipelines. A dedicated survey that provides a focused analysis of the role, methodologies, and future of language models in VAD is therefore needed to guide researchers and practitioners in this rapidly growing area. This paper aims to fill this gap by providing an in depth survey of language model based methods for Video Anomaly Detection. We distill key concepts, categorize diverse methodologies, and outline promising directions for future research.
We present a structured and comprehensive review of the Video Anomaly Detection (VAD) domain, with a particular focus on the emerging role of language model based methods. First, we provide an overview of VAD and categorize existing methods into representative paradigms to clarify the methodological landscape and the diverse approaches used to detect anomalies in video. Second, we review widely used datasets, examining their characteristics, scale, and suitability for different VAD settings, and provide practical guidance for evaluation and benchmarking. Third, we summarize commonly adopted evaluation metrics and discuss their strengths and limitations to support fair and consistent comparisons.
Building on this foundation, we examine language model based VAD methods in detail, organizing the discussion according to the categories introduced earlier. For each category, we highlight key developments and design choices that distinguish LM based approaches. We also include selected seminal and state of the art non LM methods to provide context and enable meaningful comparisons.
Furthermore, we expect LM-based VAD research to continue evolving rapidly as new MLLMs, prompting strategies, instruction-tuning datasets, open-vocabulary protocols, and anomaly-understanding benchmarks emerge. For this reason, we do not treat this survey as a fixed snapshot of the literature. Instead, following the dynamic survey perspective [36], we frame this work as a living scholarly document whose content can be maintained over time while preserving a stable taxonomy and narrative structure. In a traditional static survey, the literature coverage begins to degrade immediately after publication as new papers appear. In contrast, a dynamic survey aims to reduce obsolescence by periodically integrating relevant new work into the existing organization rather than requiring the community to repeatedly produce overlapping surveys on the same topic. This distinction is particularly important for LM-based VAD, where the pace of publication is high and methodological categories are still actively forming.
Concretely, the taxonomy and paper coverage in this survey are designed to support versioned revisions. Future updates may add newly published methods, revise method categorizations, expand dataset and metric tables, and correct metadata, while keeping the high-level structure of the survey stable unless a major human-guided revision is warranted. This update philosophy follows three principles: updates should be localized to the relevant section, conservative with respect to existing text and organization, and transparent through version records. By adopting this dynamic format, the survey aims to remain useful beyond its initial publication date and to provide a continuously maintained reference for researchers working on language-model-based video anomaly detection. Table 2 positions our survey with respect to existing VAD surveys by comparing their scope, benchmark discussion, treatment of advanced LM-based VAD topics, and support for dynamic survey design.
The main contributions of this survey can be summarized as follows:
- We provide a focused and systematic survey of language-model-based video anomaly detection, emphasizing how LLMs and MLLMs enable semantic reasoning, contextual understanding, open-vocabulary recognition, and anomaly explanation. - We organize LM-based VAD methods into a unified taxonomy across supervision and deployment paradigms, including fully supervised, unsupervised, semi-supervised, weakly supervised, training-free, instruction-tuned, and open-world/open-vocabulary settings. - We position LM-based methods relative to selected seminal and state-of-the-art non-LM foundations, clarifying how recent language-driven approaches extend, modify, or depart from conventional VAD pipelines. - We review representative VAD datasets and evaluation protocols, highlighting their annotation granularity, semantic richness, and suitability for benchmarking both anomaly detection and anomaly understanding. - We present the survey as a dynamic, versioned scholarly resource whose taxonomy, method coverage, dataset discussion, and evaluation analysis can be periodically maintained as the field evolves. - We identify key limitations, open challenges, and future research directions for robust, interpretable, efficient, and generalizable language-model-based VAD systems.
TABLE 2. Comparison of recent VAD survey papers in terms of scope, benchmark discussion, advanced LM-based topics, and dynamic survey design. ✓ indicates clear coverage, ∼ indicates partial coverage, and ✗ indicates that the aspect is not a major focus.
| Survey | Year | Focus | LM/MLLM Focus | Multi-Paradigm Coverage | Benchmark Analysis | Advanced LM-VAD Topics | Dynamic / Versioned |
|---|---|---|---|---|---|---|---|
| Ramachandra et al. [27] | 2020 | Single-scene semi-supervised VAD | ✗ | ✗ | ✓ | ✗ | ✗ |
| Nayak et al. [28] | 2021 | Deep learning-based VAD methods | ✗ | ✗ | ✓ | ✗ | ✗ |
| Tran et al. [29] | 2022 | Image and video anomaly analysis | ✗ | ∼ | ✓ | ✗ | ✗ |
| Liu et al. [30] | 2024 | Generalized VAD taxonomy | ✗ | ∼ | ✓ | ✗ | ✗ |
| Wu et al. [31] | 2024 | VAD with initial large-model topics | ∼ | ✓ | ✓ | ∼ | ✗ |
| Abdalla et al. [32] | 2024 | Decade review of deep VAD | ∼ | ✓ | ∼ | ∼ | ✗ |
| Ding et al. [33] | 2024 | LLMs and VLMs in VAD | ✓ | ∼ | ∼ | ∼ | ✗ |
| Liu et al. [34] | 2025 | Networking systems for VAD | ✗ | ✗ | ∼ | ✗ | ✗ |
| Gao et al. [35] | 2025 | Evolution of VAD from DNNs to LLMs | ✓ | ✓ | ✓ | ∼ | ✗ |
| Ours | 2026 | Language-model-based VAD with dynamic survey design | ✓ | ✓ | ✓ | ✓ | ✓ |