D. Instruction Tuning Based Video Anomaly Detection#
Instruction-tuned language-model-based VAD adapts LLMs or MLLMs to anomaly detection through task-specific instruction data, rather than relying solely on frozen foundation models at inference time. In contrast to training-free methods, which use pretrained models through prompting, captioning, or retrieval without updating model parameters, instruction-tuned approaches explicitly align the model with VAD-oriented objectives such as anomaly prediction, temporal localization, abnormal event description, and explanation generation. The required supervision may come from manually annotated instructions, video-level labels, pseudo-instruction data, generated captions, question-answer pairs, or anomaly explanations. This paradigm is attractive because instruction tuning can make MLLMs more responsive to anomaly-specific queries and better suited for complex reasoning, dialogue-style interaction, and fine-grained abnormal event understanding. However, it also reintroduces dependence on curated or generated training data, making these methods less annotation-free than training-free approaches and more sensitive to the quality, coverage, and bias of the instruction data used for adaptation.
A first group of instruction-tuned methods focuses on improving anomaly detection while producing natural-language explanations or interactive responses. Holmes-VAD [122] is representative of this direction. It constructs VAD-Instruct50K, a multimodal instruction-tuning benchmark that combines single-frame temporal annotations, event-level video clips, captions, and anomaly-aware explanatory conversations. Based on this dataset, Holmes-VAD trains a temporal sampler to select anomaly-responsive frames from long untrimmed videos and fine-tunes a multimodal LLM with LoRA to generate anomaly judgments and explanations. In this way, the model addresses both "when" the anomaly occurs and "what/why" the event is abnormal, reducing the gap between score-based VAD and interpretable anomaly analysis. HAWK [140] extends this idea toward open-world anomaly understanding by fine-tuning a VLM on anomaly descriptions and question-answer pairs collected from multiple VAD datasets, while explicitly incorporating motion information and motion-language supervision to better describe abnormal events. AssistPDA [141] further shifts the setting from offline analysis to online surveillance assistance, unifying anomaly prediction, detection, and analysis in streaming videos through VAPDA-127K and a spatiotemporal relation distillation module. Together, these methods show that instruction tuning can transform language-model-based VAD from a frame- or segment-level scoring task into an interactive anomaly-understanding system capable of localization, explanation, question answering, and real-time assistance.
A second approach emphasizes anomaly reasoning rather than only detection or explanation generation. Vad-R1 [142] is representative of this direction. It introduces the task of Video Anomaly Reasoning, where an MLLM is expected to explicitly reason about abnormal events before producing the final answer. To guide this process, Vad-R1 designs a Perception-to-Cognition Chain-of-Thought, which first performs global and local perception of the video scene and suspicious clips, and then moves to shallow and deep cognition by identifying the abnormal event, explaining why it violates expected behavior, and reasoning about possible consequences. Based on this structure, the authors construct VadReasoning, a dataset containing CoT-style anomaly reasoning annotations as well as weak video-level labels. The model is trained in two stages: supervised fine-tuning on reasoning-annotated videos, followed by reinforcement learning with AVA-GRPO, which introduces an anomaly verification reward by checking whether removing the predicted abnormal segment changes the model's judgment. VAU-R1 [143] further develops this reasoning-oriented direction through reinforcement fine-tuning. It decomposes video anomaly understanding into multiple-choice question answering, temporal anomaly grounding, anomaly reasoning, and anomaly classification, and applies GRPO with task-specific rewards for output format, answer correctness, and temporal localization accuracy. Compared with standard supervised fine-tuning, this reinforcement-tuned formulation aims to improve both structured reasoning and generalization across anomaly scenarios. Together, Vad-R1 and VAU-R1 extend instruction-tuned VAD from generating post-hoc descriptions toward explicit anomaly reasoning, where temporal localization, anomaly category prediction, causal explanation, norm-violation analysis, and reward-guided reasoning are jointly considered.
A third group extends instruction-tuned language-model-based VAD toward long-term, multi-scene, and multi-granular anomaly understanding. Figure 5 illustrates an instruction-tuned MLLM-based VAD pipeline with anomaly-focused temporal sampling.
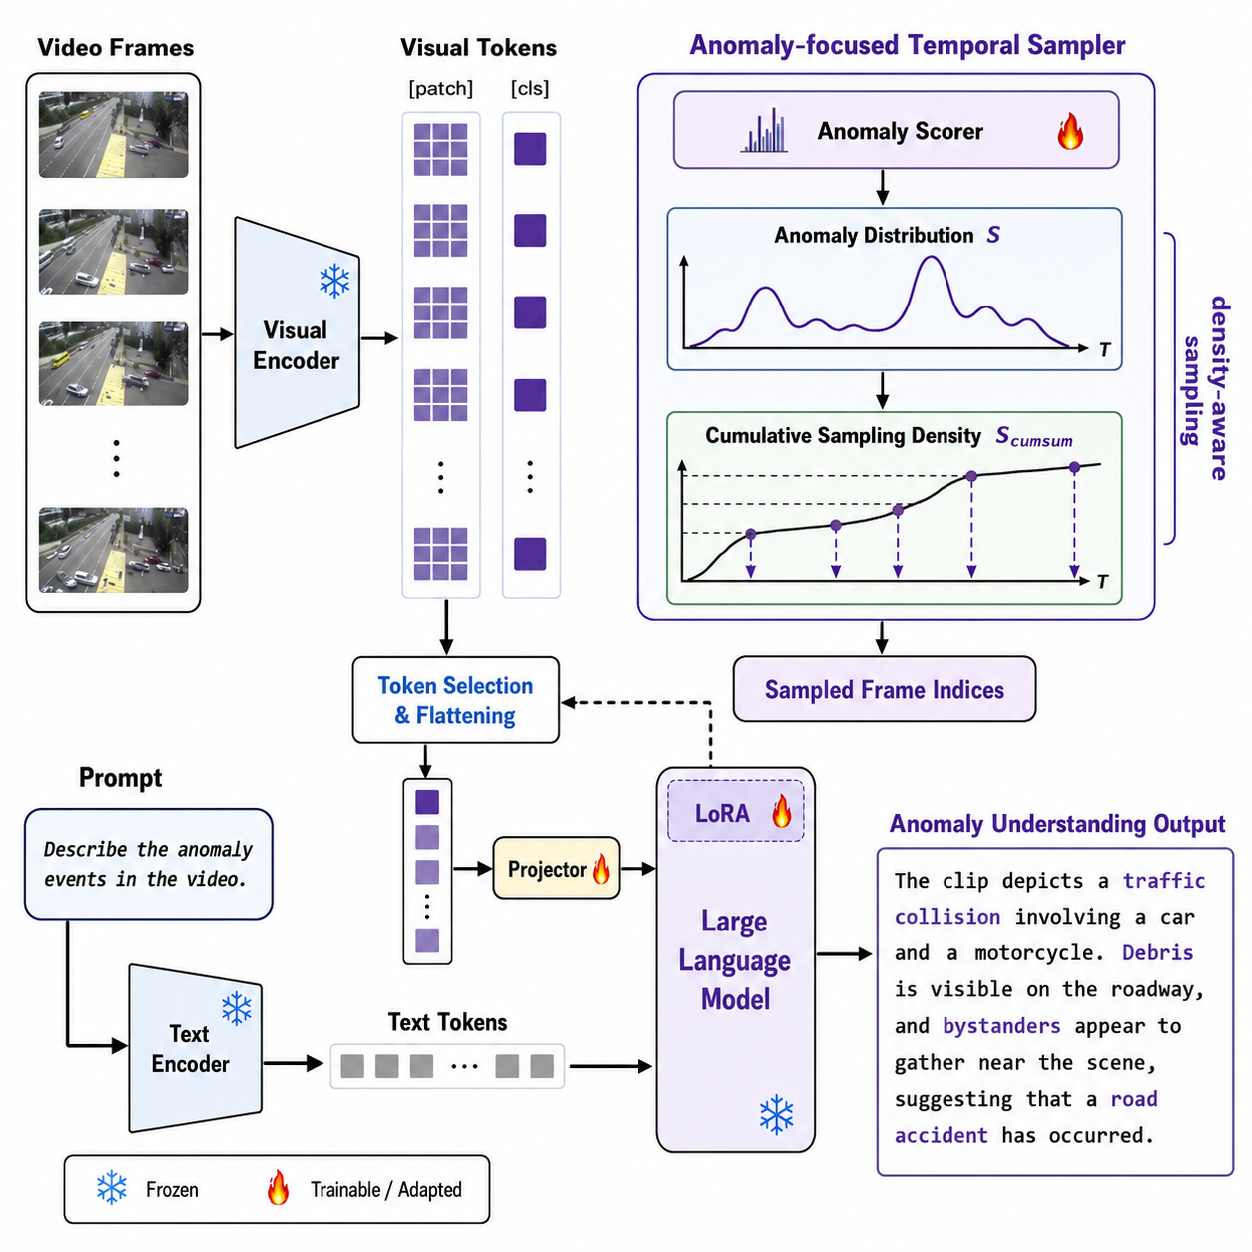
Holmes-VAU [61] is representative of the long-term and any-granularity direction. It introduces HIVAU-70K, a hierarchical instruction benchmark with clip-level, event-level, and video-level annotations, enabling models to learn both short-term visual perception and longer-term anomaly reasoning. To process long videos efficiently, Holmes-VAU further proposes an Anomaly-focused Temporal Sampler that uses anomaly scores to adaptively select informative frames, allowing the MLLM to focus on anomaly-rich regions rather than uniformly sampled frames. This design extends instruction-tuned VAD from isolated clip-level explanation toward hierarchical video anomaly understanding across multiple temporal scales. Sherlock [144] addresses a related but more structured formulation through the Multi-scene Video Abnormal Event Extraction and Localization task, where the model must localize the abnormal event and extract a quadruple consisting of subject, event type, object, and scene. To support this task, Sherlock introduces a global-local spatial-sensitive LLM with spatial experts for action, object relation, background, and global context, together with a spatial imbalance regulator to balance these heterogeneous cues. Together, Holmes-VAU and Sherlock show that instruction-tuned anomaly models are moving beyond binary detection and single-clip explanation toward long-video understanding, multi-granularity reasoning, multi-scene event localization, and structured semantic extraction.