C. Training-Free Video Anomaly Detection#
Training-free language-model-based VAD studies the use of frozen LLMs, VLMs, or MLLMs for anomaly detection without task-specific fine-tuning or optimization on VAD datasets. Unlike weakly supervised methods, which typically train MIL-based detectors using video-level labels, training-free approaches rely on the pretrained semantic and reasoning capabilities of foundation models. In this setting, anomaly detection is often performed through caption generation, prompt-based reasoning, text-video similarity, rule-based scoring, temporal aggregation of language descriptions, or direct MLLM questioning. This paradigm is attractive because it reduces annotation and training costs, improves flexibility across scenes and anomaly categories, and can provide natural-language explanations alongside anomaly scores.
However, training-free VAD also introduces distinct challenges. Since the models are not adapted to the target surveillance domain, their performance depends heavily on the quality of visual descriptions, prompt design, temporal sampling, and the ability of the language model to distinguish rare abnormal events from unusual but benign activities. In addition, frozen MLLMs may hallucinate objects or actions, overlook subtle temporal changes, or produce inconsistent judgments across frames. Therefore, recent training-free methods differ mainly in how they convert video into language-aware evidence and how they aggregate this evidence into reliable anomaly decisions. Representative works explore frame or clip captioning with LLM-based temporal reasoning, verbalized anomaly scoring, customizable zero-shot anomaly definitions, event-aware prompting, memory-based real-time reasoning, and multimodal caption-aware analysis.
Figure 4 shows a representative training-free LM-based VAD pipeline.
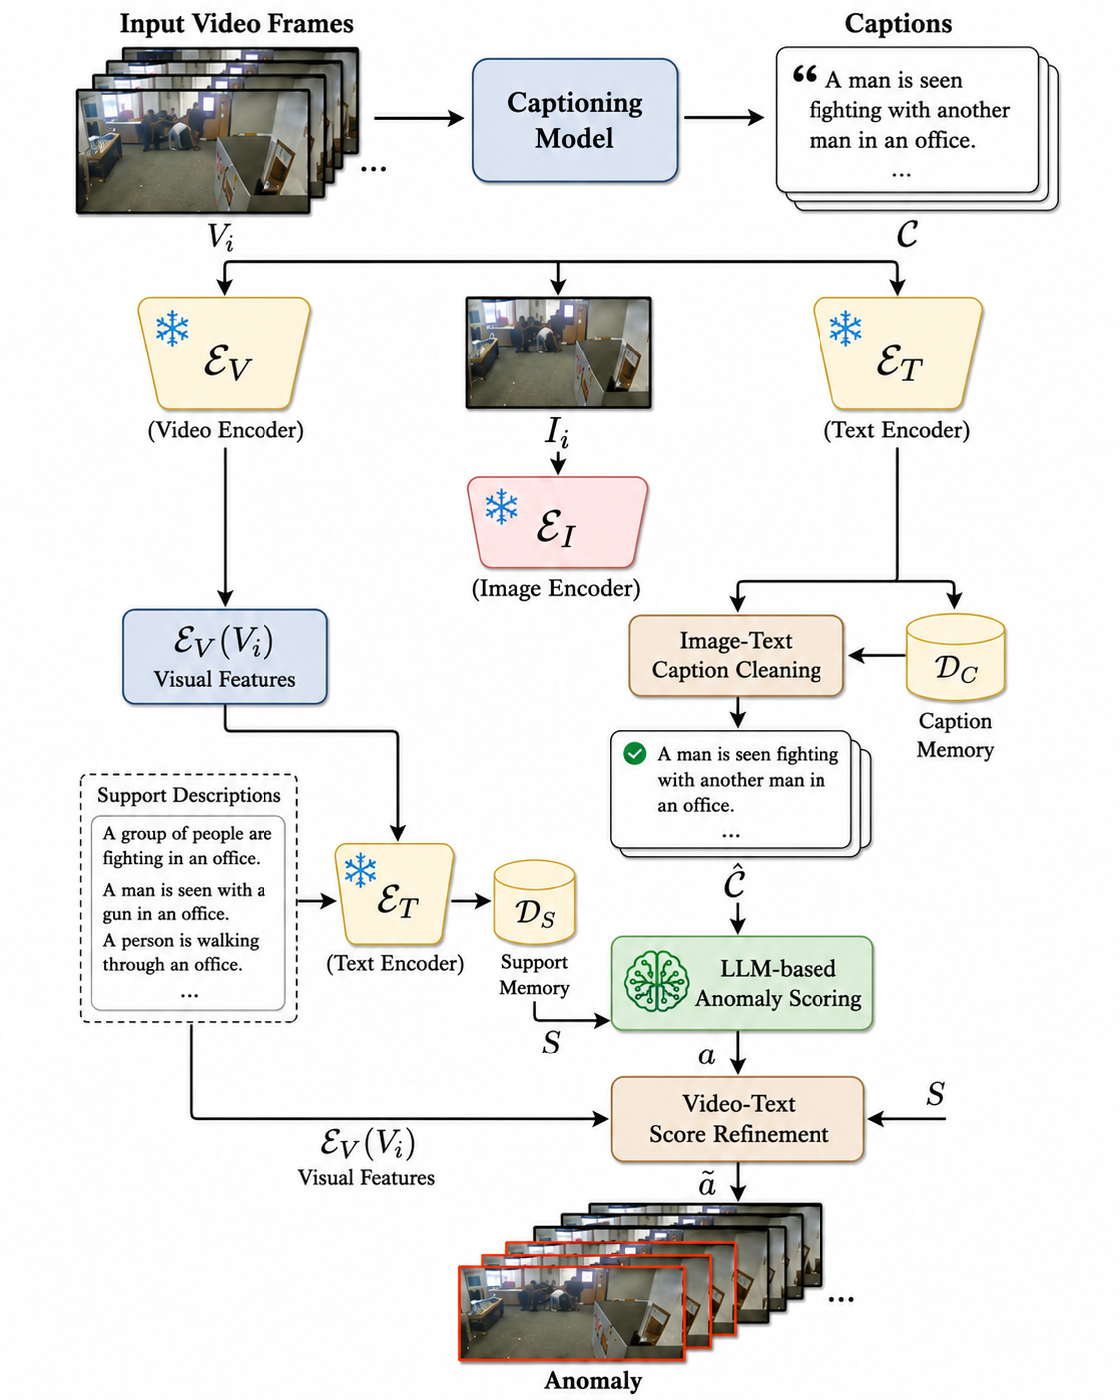
LAVAD [118] is a representative method in the training-free language-model-based VAD paradigm. Instead of training a task-specific anomaly detector, LAVAD uses frozen foundation models to convert video anomaly detection into a language-based reasoning problem. The method first generates frame-level captions using an off-the-shelf VLM-based captioning model and then applies image-text similarity to replace noisy captions with more semantically aligned descriptions from the same video. To incorporate temporal context, an LLM summarizes captions within a temporal window and assigns anomaly scores based on the resulting scene description. Finally, LAVAD refines these LLM-generated anomaly scores by aggregating scores from semantically similar video-text pairs using cross-modal similarity. This design allows LAVAD to perform temporal anomaly localization without VAD-specific training data, while also highlighting the main challenges of training-free methods: dependence on caption quality, prompt design, temporal summarization, and the reliability of frozen VLM/LLM representations.
Following LAVAD, several works further improve training-free VAD by strengthening semantic reasoning, explainability, and temporal/event modeling. VERA [130] addresses explainable VAD by learning natural-language guiding questions that elicit anomaly-relevant reasoning from frozen VLMs, avoiding instruction tuning or model-parameter updates while still adapting the prompt space using coarsely labeled data. SUVAD [131] instead emphasizes semantic understanding with MLLMs: it generates textual descriptions of normal and abnormal events, compares test-video descriptions against these event lists, and supports flexible adjustment of anomaly definitions together with explanatory outputs. EventVAD [127] focuses on the temporal limitation of frame-level MLLM reasoning by segmenting long videos into event-consistent units through dynamic spatiotemporal graph modeling, statistical boundary detection, and hierarchical prompting before anomaly scoring. MCANet [132] extends this direction with multimodal caption-aware analysis, combining visual, audio, and language cues for training-free anomaly detection. Together, these methods show that training-free VAD is moving from simple caption-to-score pipelines toward more structured semantic reasoning, where prompts, event boundaries, captions, and multimodal cues are used to make frozen foundation models more reliable for temporal anomaly localization.
Another group of training-free methods focuses on zero-shot and customizable anomaly reasoning, where the anomaly definition can be specified through natural language rather than fixed by training data. AnyAnomaly [133] is representative of this direction. It formulates customizable VAD, where user-provided text defines the abnormal event to be detected, and performs segment-level context-aware VQA with an LVLM without fine-tuning. To reduce latency and improve temporal reasoning, AnyAnomaly selects key frames from each video segment, constructs position context to emphasize text-relevant regions, and builds temporal context in a grid format to capture action changes over time. This design enables the method to detect user-defined abnormal objects, actions, or behaviors across different environments without retraining. More broadly, Anomaly-OV [134] studies zero-shot anomaly detection and reasoning with MLLMs in image-based anomaly inspection, introducing anomaly-specific instruction data and a specialist visual assistant that selects suspicious visual tokens for detection and explanation. Although Anomaly-OV is not a standard VAD method, it reflects a related trend toward open-ended anomaly reasoning, where foundation models are expected not only to score abnormality but also to describe fine-grained anomalous evidence and explain why an observation is abnormal. Related works further extend this direction through hybrid prompt personalization [135], CLIP-assisted zero-shot anomaly scoring [136], and generic GPT-4V-based anomaly understanding [137]. Together, these methods broaden training-free VAD from fixed benchmark anomaly categories toward user-defined, prompt-driven, and explanation-oriented anomaly reasoning.
Beyond general training-free and customizable VAD, recent works also explore memory-based, real-time, pseudo-labeling, agentic, and application-specific extensions. Flashback [124] is representative of the memory-driven and real-time direction. Instead of invoking an LLM during inference, Flashback first constructs an offline pseudo-scene memory by using an LLM to generate normal and anomalous scene captions, which are then embedded with a frozen cross-modal encoder. During online inference, incoming video segments are matched against this memory through similarity search, and the retrieved captions provide both anomaly scores and textual explanations. This retrieval-based design removes expensive online LLM calls and enables real-time zero-shot VAD, while repulsive prompting and scaled anomaly penalization are used to reduce bias toward anomalous captions. Other works extend training-free LM-based VAD in complementary ways: training-free VLM-based pseudo-label generation [125] uses foundation models to generate auxiliary supervision for downstream VAD, VisionGPT [138] applies LLM-assisted anomaly detection to safe visual navigation, PANDA [128] and Qvad [123] explores agentic AI pipelines for generalist VAD, and robotic VAD [139] studies VLM-based anomaly detection in scientific laboratory environments. These extensions show that training-free language-model-based VAD is expanding from benchmark-centered anomaly localization toward practical deployment settings involving real-time constraints, pseudo-supervision, agentic automation, and domain-specific anomaly understanding.
TABLE 6. TF-VAD methods on UCF-Crime (UCF), XD-Violence (XD) and UBnormal (UB).
| Method | Year | UCF (AUC) | XD (AP) | UB (AUC) |
|---|---|---|---|---|
| *Open World and Instruction Tuning Methods* | ||||
| OVVAD [119] | 2024 | 86.40% | 66.53% | 62.94% |
| Anomize [120] | 2025 | 84.89% | 69.31% | - |
| PLOVAD [121] | 2025 | 87.06% | - | - |
| Holmes-VAU [61] | 2025 | 88.96% | 87.68% | - |
| Holmes-VAD [122] | 2024 | 89.51% | 90.67% | - |
| *Full training-free pipelines* | ||||
| QVAD [123] | 2026 | 84.28% | 68.53% | 79.60% |
| Flashback [124] | 2025 | 87.30% | 75.10% | - |
| TFPLG [125] | 2025 | 87.52% | 85.08% | - |
| MoniTor [126] | 2025 | 82.57% | 55.01% | - |
| EventVAD [127] | 2025 | 82.03% | 64.04% | - |
| PANDA [128] | 2025 | 84.89% | 70.16% | 75.78% |
| VADTree [129] | 2025 | 84.74% | 68.85% | - |
| VERA [130] | 2025 | 86.55% | 70.11% | - |
| SUVAD [131] | 2025 | 83.90% | 70.10% | - |
| MCANet [132] | 2024 | 82.47% | 69.72% | 62.94% |
| LAVAD [118] | 2024 | 80.28% | 62.01% | 64.23% |